Process Audit Red Flags That Signal Automation Will Fail
Broken processes amplify through automation without a readiness audit.
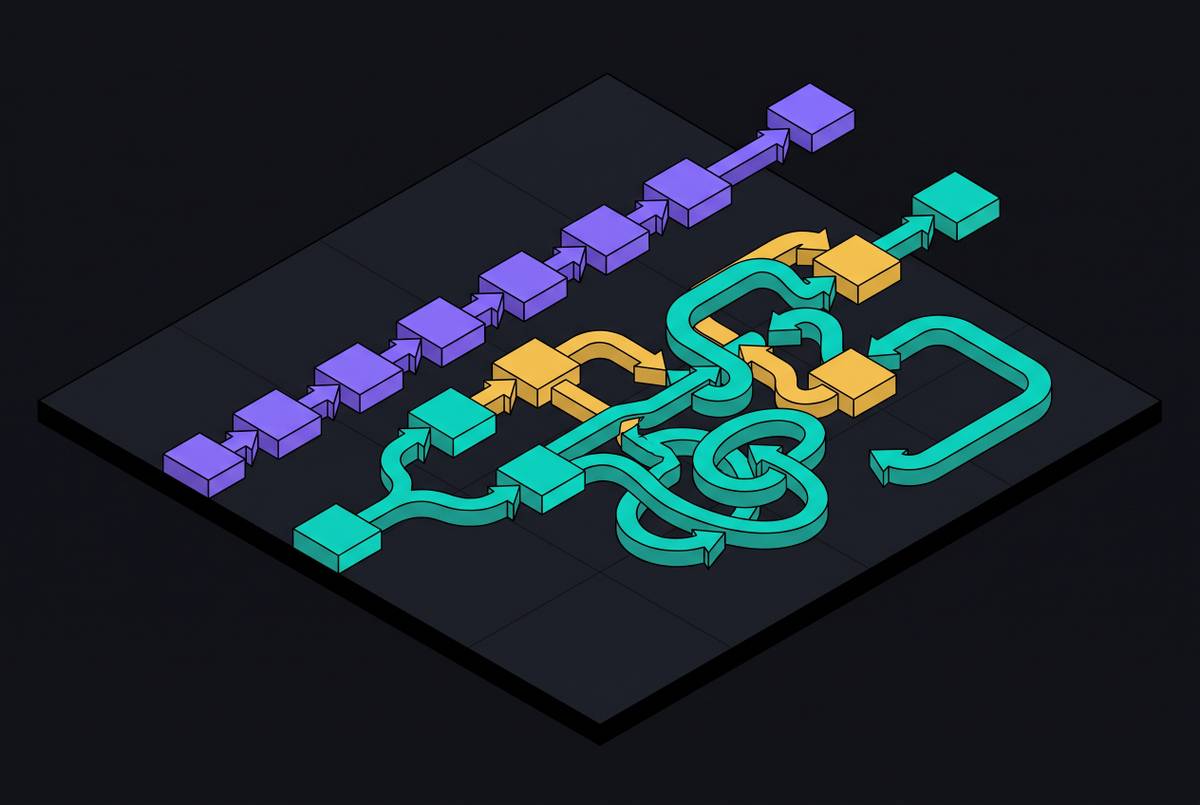
Automation does not repair a broken process. It enforces whatever logic the process already runs on, at whatever speed the new system can manage. A process with a defect built into it produces that same defect at scale. The mechanism is straightforward: before automation, informal human correction absorbs process gaps quietly, the colleague who notices the missing field, the supervisor who catches a misrouted request. Automation removes that layer of quiet correction. The defects it was catching do not disappear with it. They become structural, and they compound with every cycle the automated process runs, because nothing stands between the gap and the output anymore. Most organizations do not discover that their process was broken until the automation has already touched their data, their integrations, and the habits of the team working alongside it, and by then, rearchitecting costs far more than fixing the process would have cost beforehand.
Automation amplifies whatever process it finds, broken or not
Deloitte's AI Pulse Check, a poll of nearly 3,700 professionals, found that 48% of organizations have introduced AI without redesigning the workflows or roles it sits within. Only a small minority report redesigning at scale, with a genuinely new operating model behind the deployment. The rest have simply layered AI onto process maps that were drawn up before AI was part of the picture. Deloitte's own conclusion is that this produces more than slower execution: organizations running AI on pre-AI process maps face structurally higher costs and less flexibility over time, as competitors who did redesign around AI-native workflows pull ahead. That distinction matters because it reframes the entire problem. A tool that executes a flawed process correctly is not malfunctioning.
What a process audit is doing when it looks for automation readiness
A process audit for automation readiness is a structured investigation into whether a process has the specific properties automation requires: consistent inputs, explicit decision rules, mapped exceptions, and traceable data. That audit asks different questions than a standard operational review asks. Can the process be described the same way by every person who runs it? What happens when a case does not fit the standard path, and how often does that actually happen? Where does a human currently substitute judgment for a rule that does not exist? What data does the process consume, and can that data be traced, versioned, and validated back to its source?
Deloitte's Pulse Check recommends auditing for process change rather than tool uptake, tracking whether AI changes decisions, handoffs, cycle time, and quality, rather than simply measuring how fast the existing steps now run. That recommendation only makes sense if the audit happens before deployment. An audit conducted after the fact can tell an organization what went wrong. An audit conducted before deployment can prevent the problem before it happens. The output of a readiness audit is a set of specific red flags, each one tied to a known failure mode, and finding even one of them is reason enough to rebuild the process before any automation touches it.
The process cannot be consistently described by the people who run it
The most basic red flag an audit can find is also the most consequential: if two people who run the same process describe it differently, or produce different outputs from identical inputs, there is no single process to automate. There are multiple informal processes operating under one shared name, each shaped by whoever happens to be running it that day. Automation has to pick one version of that process to encode. It will break on the other version's inputs, and when it does, the result will look like a correctly functioning tool executing the wrong logic for a meaningful share of real cases, not a crashed system throwing errors.
The audit method for finding this is direct: ask every person who runs the process to walk through it independently, then compare the accounts. Disagreements on sequence, on where decisions get made, or on what the expected output looks like all reveal where standardization never actually happened, no matter what the org chart implies. This problem is distinct from a documentation gap. A process can have a fully written standard operating procedure and still be run inconsistently, because the SOP was written by someone who does not actually run the process, or because it was never updated once the real work drifted away from what the document describes.
Field operations make this especially visible. In construction and manufacturing, informal workarounds accumulate over years: crews adapt to site conditions the process map never anticipated, engineers route around approval steps that are too slow to wait for, and the gap between what the process map shows and what the crew actually does widens silently, with no single moment where anyone decided to deviate. Auditing the declared process tells an organization almost nothing about this gap. Auditing the field process, the one crews actually run, is the only way to find it.
Decision points that currently resolve as "it depends" or "ask someone"
Every step in a process that resolves through personal judgment, tribal knowledge, or an informal escalation, "check with the project manager," "depends on the client," is an undefined decision point. Automation will handle that point in one of three ways: it will freeze waiting for input that was never formally required, it will apply a default answer, or it will bypass the step. None of those outcomes is acceptable in a workflow that actually matters to the business.
The failure pattern follows a consistent shape. Before automation, a person standing at that decision point made a reasonable judgment call, drawing on context the system never captured. After automation, the workflow either stalls because it is waiting on a formal input nobody ever defined, or it forces through a default answer that happens to be wrong for a meaningful share of cases, confidently and without flagging the uncertainty. A customer service chatbot deployed by an airline offers a documented example of exactly this pattern: the agent gave a customer incorrect guidance on bereavement fare rules because that exception logic had never been formally encoded into the system, and the airline was ultimately found liable for the chatbot's answer. Chatbots are not the problem here. An exception rule nobody wrote down cannot be enforced by a system that only knows what it has been told.
The audit technique for this red flag is to map every "it depends" in the process and ask, specifically, what it depends on. If the answer cannot be written down as a rule that any system could apply consistently, the decision point is unresolved, and the process is not ready for automation regardless of how well-defined the rest of it looks. Construction offers a sharp example: energization readiness decisions often depend on informal coordination between procurement, commissioning, and field teams, with no documented rule for when conditions have actually been met. Automating the status reporting layered on top of that coordination produces confident-looking outputs that do not reflect whether the site is actually ready.
Exception handling that exists in practice but has never been mapped
Automating the happy path while leaving exception handling informal does not reduce the burden those exceptions create. It moves that burden downstream, past the point where the team could catch it early, and hands it to whoever discovers the automation's mistake after the fact. Most teams badly underestimate how often exceptions actually occur. An exception that feels rare in memory, because people only recall the ones that caused visible trouble, may in fact be occurring in a substantial share of total cases once someone actually counts them. Automation will encounter every one of those cases, not just the memorable ones.
In logistics and manufacturing, exceptions are where margin gets lost: material shortages, rework loops, rush orders, engineering changes made mid-build. These are precisely the cases automation is supposed to help resolve, and they are the ones that get skipped when exception paths were never mapped. The audit method here is to count exception frequency before committing to an automation design. If the exception rate is high enough that the manual cleanup required after automation cancels out the time the automation was supposed to save, the process is not ready for automation in its current form, regardless of how much faster the happy path runs.
Human-in-the-loop decision-making functions as an essential governance mechanism in current AI workflow design, not as a stopgap but as a deliberately engineered escalation path. A process that has never mapped its own exceptions has no basis for designing that escalation path, because nobody can specify what should trigger it or who should receive it. The second-order failure that follows is sharp: when exceptions are not mapped, the automation has no fallback built in. It either fails silently, proceeding on wrong or incomplete data as though nothing were amiss, or it fails loudly, halting the workflow entirely with no defined path back to a human who can resolve it.
Data quality and provenance problems that will compound under automation
A process can be well-documented, consistently run by every person who touches it, and fully mapped for exceptions, and still fail under automation if the data it consumes is inconsistent, untraced, or structured in ways the system cannot reliably parse. Data quality operates upstream of everything the rest of the audit checks, and failures there undermine conclusions drawn from every other part of the review.
A specific and common failure mode involves timestamps that reflect when data was entered rather than when the underlying event actually occurred, a pattern common in manufacturing, where backflushed or reconstructed records get treated as though they were captured live. A second failure mode involves data that varies in structure or naming convention across sources. A CRM, an ERP, and a field system that each use a different identifier for the same entity will produce matching failures under any automation that tries to join them, and those failures will not always announce themselves, they will quietly misroute or misattribute records instead.
Audit guidance for AI-embedded financial operations identifies four specific vulnerabilities to treat as a checklist: AI-generated estimates without documentation of the model inputs and assumptions behind them; revenue or outcome data that cannot be traced back to its source system; API-fed data that passes through multiple systems without traceable metadata; and AI models that update without version control, which makes comparing one period's results to the last impossible. Each of these functions as a proxy for a process that will produce unverifiable outputs once it runs at automated scale. In construction, a change order that appears in billing before its approval was documented, or a waiver that does not match the payment it was meant to support, signals that field evidence has been reconstructed after the fact. An automation built on top of that reconstructed data will reproduce the same reconstruction error, just faster and across more transactions.
Apply this test here: can every data input to this process be traced to its source, timestamped at the moment of capture, and verified as accurate before the process consumed it? Wherever the answer is no, that input is a data gap that will cause the automation to produce confident-looking outputs built on a foundation nobody can actually stand behind.
Integration dependencies that are assumed rather than verified
Many automation designs assume that the systems a process depends on, the ERP, the CRM, the field data platform, the billing system, are already integrated and already producing consistent, real-time data. A process audit has to verify that assumption directly: that these integrations exist, that they hold up under production load rather than just pilot conditions, and that they produce data in the exact format the automation requires to function.
The failure pattern here is specific. Automation gets built against an integration that works cleanly in a pilot and breaks once production volume hits it, or it gets built against a data feed that the automation parses correctly most of the time and incorrectly for a meaningful minority of cases, cases that often cluster around exactly the exceptions the rest of the audit was meant to catch. Warren Averett's audit guidance describes one concrete version of this failure: when data flows through multiple APIs without records of its source, its capture time, or its modification history, auditors cannot confirm its accuracy or completeness. The automation inherits the same blindness. It cannot verify what the audit trail does not contain.
Logistics environments show this clearly. Local tools for quality, maintenance, energy, and production each operate correctly in isolation, but they rarely agree with each other on what should happen next, because they were never designed to coordinate automatically. Automating a workflow that depends on that coordination, without first verifying the integration between those tools, produces a system that runs cleanly in a demo and breaks once it meets the full complexity of production. The audit action that catches this before deployment is to map every system the process depends on, trace every handoff of data between them, and deliberately break one connection at a time to confirm the automation detects the failure and routes to a correct fallback. If no fallback exists for that broken connection, that integration is a single point of failure for the entire automated process.
Governance gaps that automation will surface, and that must be resolved before deployment
A process audit focused only on workflow structure and data quality is incomplete. It also has to establish who owns the outcome when the automation produces a wrong result, what specifically triggers a human review, and what failure rate the organization will tolerate before halting the system. Every red flag covered above, inconsistent process description, unresolved decision points, unmapped exceptions, unreliable data, unverified integrations, becomes a governance question once automation is running in production. The only choice an organization has is whether it answers that question in advance or discovers the answer during an incident.
Deloitte's Pulse Check found that many organizations have not explicitly designed their accountability model for AI. Autonomy tends to expand one use case at a time, quietly, and the controls and escalation paths meant to govern that autonomy lag behind each expansion. The gap between what an AI system is permitted to do and how accountability for its actions is actually enforced is where enterprise risk builds, largely unnoticed, and most leaders only see that gap clearly once an exception, a failure, or an audit forces it into view.
That gap is particularly acute in agentic deployments, where systems send communications, update records, and interact directly with external APIs on their own initiative. Each of those actions produces downstream consequences, and without a designed accountability model in place, a failure that touches multiple systems at once has no clear owner and no clear path back to a correct state. An audit has to establish, concretely, who reviews AI outputs and at what frequency, and whether that review is designed to catch errors before their consequences compound or only after the damage is already done. It also has to establish what the escalation path looks like when the automation hits an exception it cannot handle, and whether that path is actually documented and staffed, or simply assumed to exist because someone, at some point, said it would.